
Which sources may be indexed?
Define ownership, access, version, retention, freshness and deletion for the corpus.
Corporate AI training · Onsite & live online
Based in Bengaluru · delivering across India
Private RAG engineering training · India-wide
Help developer teams build retrieval systems that remain measurable as documents, questions, models and indexes change.
RAG Training India is private corporate training for developer, data and AI engineering teams building Retrieval-Augmented Generation systems. It covers corpus and ingestion design, chunking, embeddings, vector and hybrid search, filtering, reranking, grounded answers, citations, evaluation, access control and production handoff. The team learns to diagnose retrieval and generation separately using representative questions and evidence. Delivery can be live online across India or onsite when agreed.
Updated
Scope boundary: Training does not guarantee accuracy, remove hallucination risk or deploy a production system. The client owns data rights, access, architecture, security, validation and release approval.
A useful programme connects document governance, retrieval evidence and answer review instead of treating RAG as one chain call.
Define ownership, access, version, retention, freshness and deletion for the corpus.
Build representative query–evidence judgements from actual user and domain needs.
Separate parsing, chunking, retrieval, reranking, context and generation errors.
Set quality, latency, cost, access and unsupported-answer criteria before rollout.
A safe client-relevant corpus can replace generic samples when authorised and prepared before delivery.
Map documents, parsing, metadata, versions, permissions and refresh.
Compare structure-aware and alternative chunk strategies for judged questions.
Establish lexical, dense or hybrid retrieval against query–evidence labels.
Apply access-aware metadata filters and reorder candidates when justified.
Generate with selected evidence, citation format and refusal behaviour.
Rerun test cases after corpus, model, prompt, chunk or index changes.
The appropriate route depends on whether retrieval is the main gap or one part of a larger application capability.
Frame the corpus, users, questions, evaluation and production boundaries.
Best for: Architects, leads and mixed technical stakeholders
Implement and evaluate a retrieval pipeline using the agreed stack.
Best for: Python developers, data and AI engineers
Use RAG within wider LangChain application and agent patterns.
Best for: Teams standardising on LangChain
Connect RAG with agents, MCP, APIs, deployment and LLMOps.
Best for: Teams needing complete application engineering
The focused route goes deeper into retrieval; the broader route connects retrieval to the rest of the system.
| Decision point | RAG-focused corporate training | Production AI Engineering |
|---|---|---|
| Primary goal | Improve retrieval and grounded-answer capability | Build and operate complete AI applications |
| Core evidence | Query–evidence set and measured RAG pipeline | Integrated projects and system-level evaluation |
| Best for | Teams with a specific knowledge-system need | Teams building RAG plus agents, APIs and deployment |
| Scope | Confirmed against corpus, stack and team level | Confirmed against the wider engineering programme |
The result is a reproducible evidence trail across data, retrieval and answers.
Source, access, version, refresh and deletion assumptions are explicit.
Representative questions link to judged evidence and failure categories.
Support, completeness, citation and refusal behaviour can be inspected.
Scale, security, latency, cost, monitoring and ownership gaps are recorded.
The route is confirmed before delivery so participants practise at the right technical level and do not confuse a tutorial demo with production readiness.
Confirm whether the need is a public learning route, a private team workshop or a broader engineering programme.
Agree programming level, accounts, model access, practice data, repository and any security restrictions.
Dates, duration, topics, exercises, delivery mode, fees and inclusions are stated before booking.
Short explanations lead into implementation, evaluation, debugging and instructor feedback.
Participants leave with reviewed artefacts, known limitations and a route for further practice or implementation.
The proposal selects artefacts that fit the team, corpus, stack and time.
Sources, users, questions, pipeline, access, evaluation and owners.
A bounded ingestion, retrieval and grounded-answer implementation.
Query–evidence labels, results, traces, errors and next experiments.
Security, data lifecycle, scale, latency, cost, monitoring and release.
The practical work keeps access, evaluation, failure handling and human authority visible.
Labs use authorised model access, safe documents and practice integrations; credentials and private data never belong in prompts or source control.
A successful demo is tested against expected, difficult and failure cases before anyone calls it reliable.
Permissions, validation, timeouts, budgets and approval gates limit what an agent or integration may do.
A qualified person reviews sources, outputs, tool calls and material actions before release or use.
The agreed framework and provider versions are checked before delivery and linked to first-party documentation.
Real instructor-led sessions from the Technovids delivery archive. The photographs show delivery context; they do not imply a result for a future cohort.


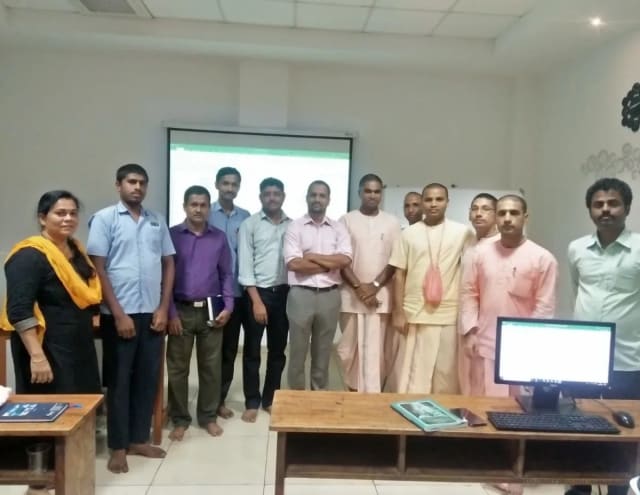
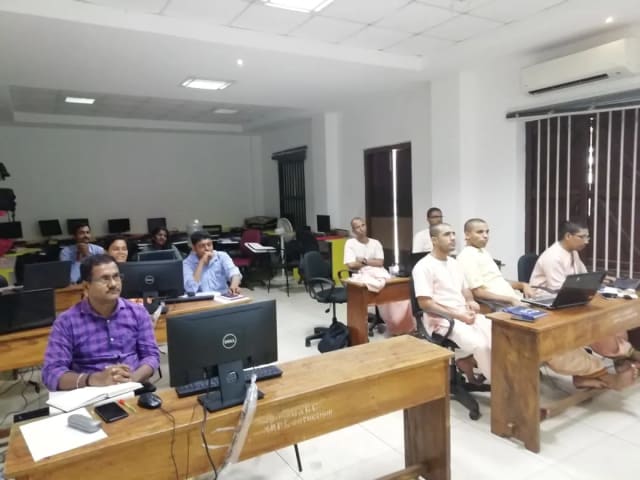


Technovids assigns a suitable trainer after the audience, subject depth and delivery needs are confirmed.
Co-founder & Lead Instructor, Technovids Consulting
Pankaj is a co-founder and the lead instructor at Technovids Consulting. His programme work spans practical AI adoption, AI engineering, evaluation, responsible production AI, data analytics and corporate learning design, with an emphasis on hands-on exercises connected to workplace tasks.
Expertise:
AI & Machine Learning Trainer, Strategist and Consultant
Junaid is an AI and machine-learning trainer, strategist and consultant with more than 22 years of training experience. His work combines enterprise AI education, business-centred adoption, responsible AI practices and applied solution design, helping professional audiences connect AI concepts to real organisational needs.
M.E. in Computer Engineering, specialising in Artificial Intelligence · author of programming books on Python, Java and C++
Expertise:
Technical Trainer & Curriculum Architect
Pradeep is a technical trainer and curriculum architect with more than 20 years of experience across enterprise technology, cloud infrastructure and advanced AI systems. He designs practitioner-focused programmes, labs and assessments covering AI, LLM systems, Python and machine learning, translating complex technical subjects into structured learning experiences.
Bachelor of Engineering in Electrical Engineering · instructor-led, virtual and blended delivery
Expertise:
The proposal names or confirms the trainer assignment for the engagement; every trainer shown here does not teach every programme.
Updated
Approved feedback and delivery photographs show wider Technovids training experience. They are not presented as guaranteed outcomes from this specific course.
Practical training programmes delivered for learners, professionals and teams across AI, data, cloud, productivity and professional skills.
What professionals found useful, practical and relevant to their day-to-day work.
The AI training from Technovids helped me gain a better understanding of Generative AI, prompt engineering, and practical AI use cases for software development. The course was clear, interactive, and focused on real-world applications. It gave me confidence to explore AI tools more effectively in my work.
Technovids conducted the AI training in a very effective and engaging manner. The sessions were practical, easy to follow, and focused on how AI can be used in real software engineering and business workflows. It was a valuable program for understanding the current direction of AI adoption in the industry.
The AI training delivered by Technovids was practical, structured, and relevant for software professionals. The sessions connected AI concepts with real industry use cases, making it easier to understand how AI can be applied in development, automation, and productivity improvement. It was a valuable learning experience.
I had been trying to transition from traditional backend development to Generative AI, but self-learning was getting overwhelming. The AI Engineering course at Technovids gave me the exact structured roadmap I needed. The modules on LLM architectures and practical prompt engineering are brilliant. It’s not just theory; you actually build functional AI applications. Highly recommend this for working professionals looking to upgrade their tech stack.
What I loved most about the Technovids GenAI program is how up-to-date the curriculum is. Instead of outdated practices, we learned to integrate the Model Context Protocol (MCP) and practically apply tools like Claude and Cursor for AI-assisted coding. It felt like I was learning the exact skills that top tech companies are hiring for right now. The pace is perfect, and the support is great.
I was initially intimidated by the math and complexity behind AI, but the trainers at Technovids explain things in such an accessible way. They break down everything from basic prompt engineering to complex integrations without losing you in the jargon. The session recordings and project materials are top-notch. If you are serious about becoming an AI Engineer, Technovids provides the perfect launchpad.
Published answers define the page scope. A written proposal records engagement-specific terms.
Software developers, data engineers, AI engineers and technical leads working on document, search or knowledge applications. Architecture-only participants can join a decision workshop; hands-on participants need programming foundations.
Yes, if the organisation owns or is authorised to use them and approves the environment, access and preparation. A safe synthetic or public corpus is the default alternative.
It can cover vector search, lexical or hybrid retrieval, metadata filtering and reranking. The specific products, depth, accounts and datasets are confirmed in the proposal.
No. Retrieval and generation can both fail. The programme teaches evidence-based retrieval evaluation, grounded-answer checks, citations, refusal and human review rather than making an accuracy guarantee.
Private delivery can be live online or onsite when agreed. The proposal confirms location, travel, facilities, participant count, lab readiness, duration and commercials.
No. Training develops skills and agreed artefacts. Production discovery, data preparation, implementation, security review, validation, integration and support require a separate scope.
2nd Floor, Chandrodaya Complex, 19/19, 24th Main Rd, near Hanuman Temple, Agara Village, 1st Sector, HSR Layout, Bengaluru, Karnataka 560102.
Please contact us before visiting the head office. The HSR Layout address is a head office, not a walk-in public classroom.