
Start here
Multimodal AI in plain language
A photograph and a written description can contain different parts of the answer. For example, an invoice image shows a charge while a note says the charge was waived. The useful task is to connect those details, not merely transcribe both.
Multimodal does not mean every medium is supported or that every architecture uses one identical processing path. Inspect the chosen model’s documented capabilities and test the actual image sizes, layouts and quality your application will receive.
How it works
Provide the media and the question
Use a readable image and ask for a specific check. Identify which document or region matters when several inputs are present.
Separate observations from interpretation
Ask for the visible fields first, then the inconsistency. An unreadable figure should remain unknown rather than become a guessed value.
Verify the result against the source
Check extracted amounts and any conclusion. For calculations, use explicit arithmetic rather than trusting a fluent explanation.
Illustrative example · Fictional data
Spotting a charge that needs checking
- Input
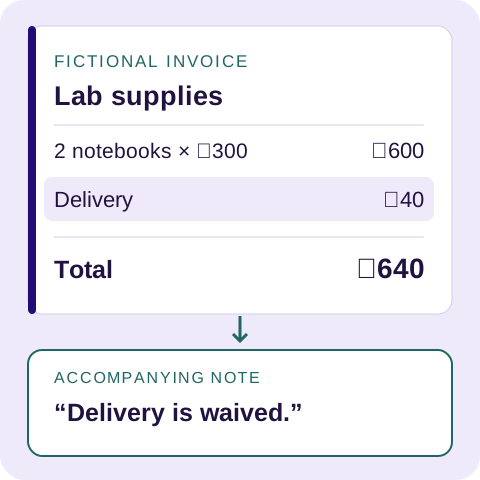
- The illustrated fictional invoice lists two notebooks at ₹300 each, delivery ₹40 and total ₹640. A separate note says delivery is waived.
- Process
- Read the line items and note. Calculate ₹600 + ₹40 = ₹640, then identify the disagreement about delivery rather than claiming the addition is wrong.
- Expected output
- “The arithmetic matches the invoice, but the ₹40 delivery charge conflicts with the note. If the waiver applies, the total would be ₹600.”
- How to check it
- The assistant must not silently rewrite the invoice. Repeat with a blurred delivery amount and require it to identify the unreadable field.
Where it helps
- Comparing visible document fields with written instructions.
- Explaining a chart while preserving its labels, units and caveats.
- Drafting image descriptions that a person can inspect and correct.
Multimodal AI, OCR and computer vision
- OCR
- Extracts text from images. Useful when transcription is the main requirement.
- Computer vision
- Works on visual tasks such as detection or segmentation. It can form part of a wider application.
- Multimodal AI
- Relates different media, such as a question and an image. It may still use OCR or specialist vision components.
Encoders, representations and document pipelines
A multimodal system converts inputs into representations that its model can process. Text may be tokenised; an image may be encoded as patches or visual features; audio may be encoded directly or transcribed first. The way those representations are combined depends on the architecture, not simply on the label “multimodal”.
For a document workflow, preserve page order, layout and links between tables and their captions. OCR can provide searchable text, while image input may preserve visual context. Neither guarantees correct extraction: scan quality, small text, merged cells and handwritten notes can change the result.
Design an API workflow around the required evidence
Confirm the model’s supported input types, file limits and output format. Request a structured extraction with page references, validate required fields and calculations, and route low-quality or conflicting evidence to review. Do not silently convert a missing field into a plausible value.
Keep the original file alongside extracted values so a reviewer can trace the answer. In the existing invoice exercise, a total should be checked against the displayed line items and currency, not accepted merely because the JSON is valid. Redact sensitive material before processing where required by the approved workflow.
Related reading and learning pathways
Common pitfalls
- Small text, rotation and poor image quality can change the extracted information.
- An image can show a visible condition without proving its cause.
- A model that understands an image does not necessarily generate images, and vice versa.
Put the idea to work
Try it yourself
Use the illustration and ask separately for the visible amounts, the arithmetic and the contradiction. Compare that with a vague “check this invoice” request and see which answer is easier to verify.
Common questions
Is multimodal AI always generative?
No. Multimodal describes the types of information used. A system can classify or retrieve across media without generating new content. For example, a model that matches product photos to catalogue descriptions is multimodal but only retrieves; it does not create new images or text.
Can a multimodal model read every chart accurately?
No. Test the charts you actually use, including small labels, unusual layouts and ambiguous legends. Verify important values against source data. Dense charts, rotated text and colour-coded legends are common sources of misreads. Where numbers drive decisions, extract them from the underlying data or spreadsheet instead of the image.
Should a document workflow use OCR or a multimodal model?
Use the task as the deciding factor. Reliable text extraction may be enough; relating layout, images and instructions may justify a multimodal component. A combined pipeline is also possible. Many teams use OCR for clean typed text and send only complex pages, forms or diagrams to a multimodal model, then compare outputs on a sample before scaling.
Your next step
Continue learning
Connected concepts
Sources and further reading
Examples on this page are teaching exercises using fictional information. They are not client case studies or measured outcomes.